Datacenter

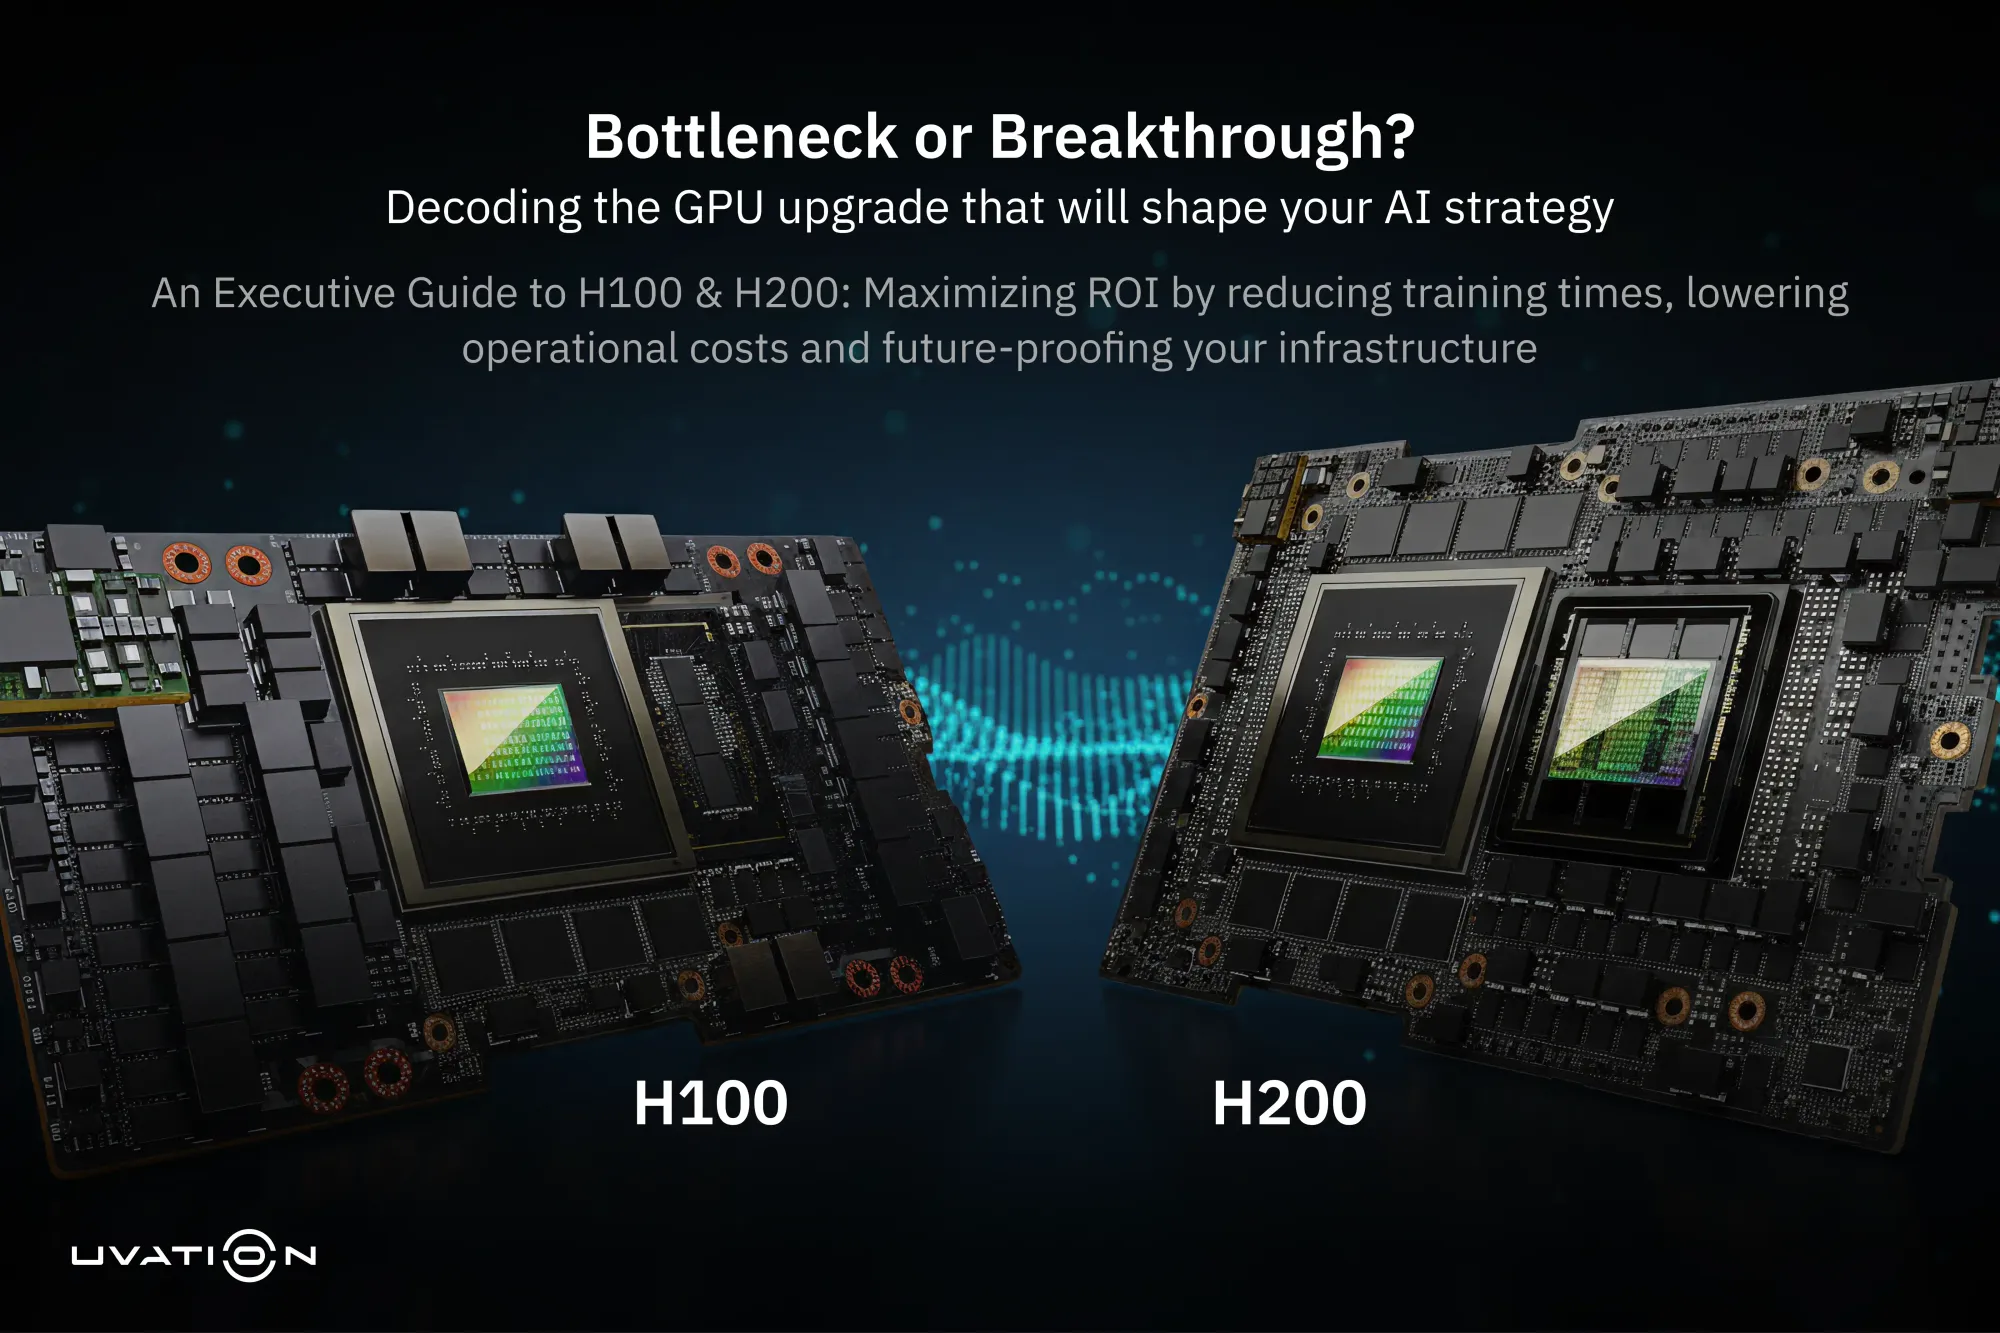
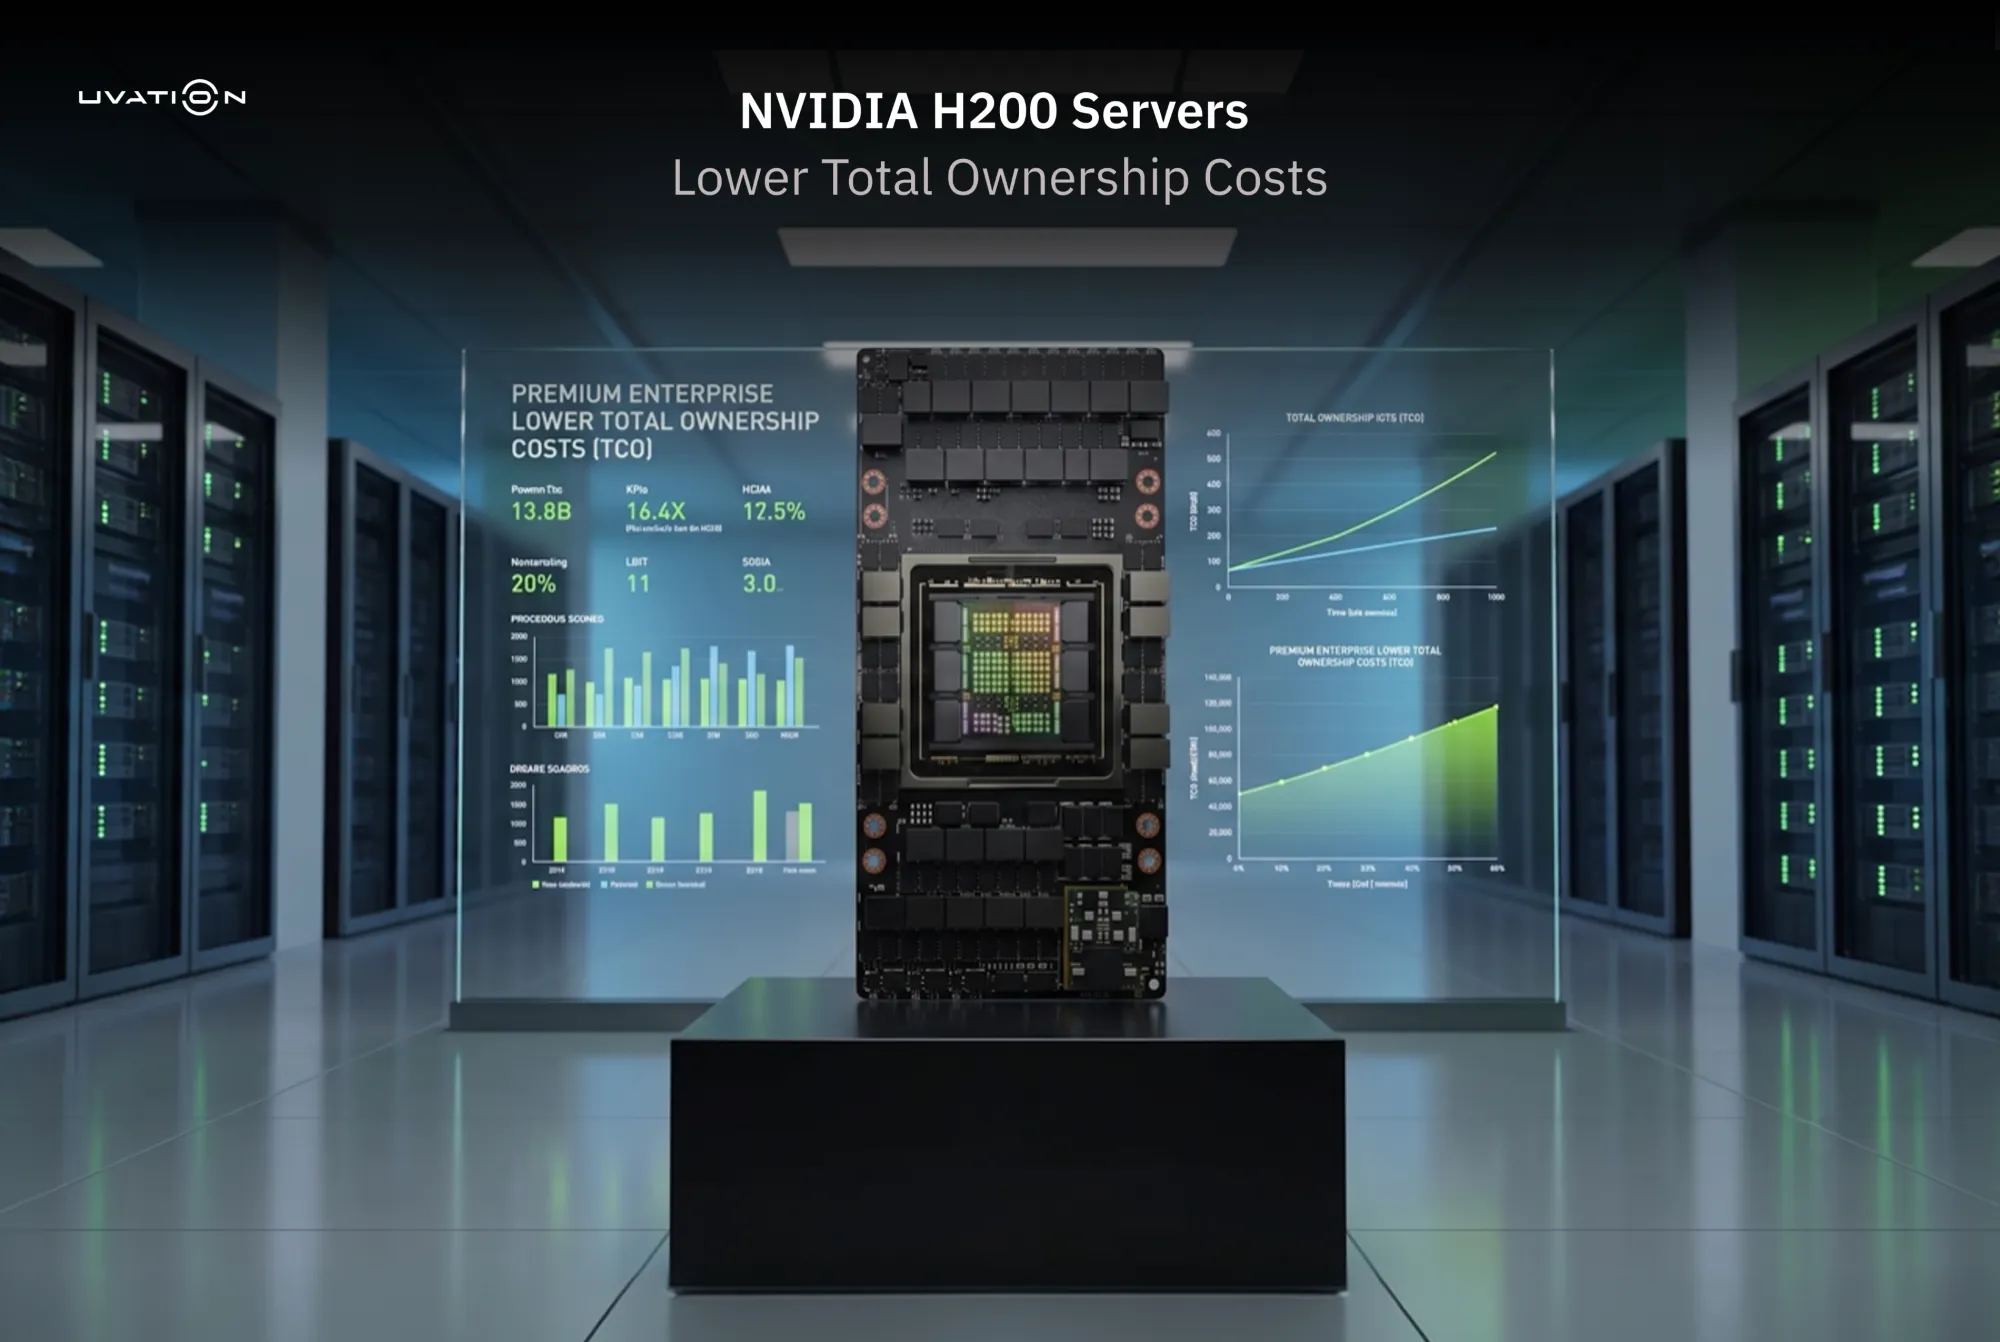
While NVIDIA H200 servers carry a higher upfront price, they deliver significant long-term savings that dramatically reduce Total Cost of Ownership (TCO). This blog breaks down how H200’s efficiency slashes operational expenses—power, cooling, space, downtime, and staff productivity—by up to 46% compared to older GPUs like the H100. Each H200 server consumes less energy, delivers 1.9x higher performance, and reduces data center footprint, enabling fewer servers to do more. Faster model training and greater reliability minimize costly downtime and free up valuable engineering time. The blog also explores how NVIDIA’s software ecosystem—CUDA, cuDNN, TensorRT, and AI Enterprise—boosts GPU utilization and accelerates deployment cycles. In real-world comparisons, a 100-GPU H200 cluster saves over $6.7 million across five years versus an H100 setup, reaching a payback point by Year 2. The message is clear: the H200 isn’t a cost—it’s an investment in efficiency, scalability, and future-proof AI infrastructure.
Subscribe to our Newsletter