Public Cloud

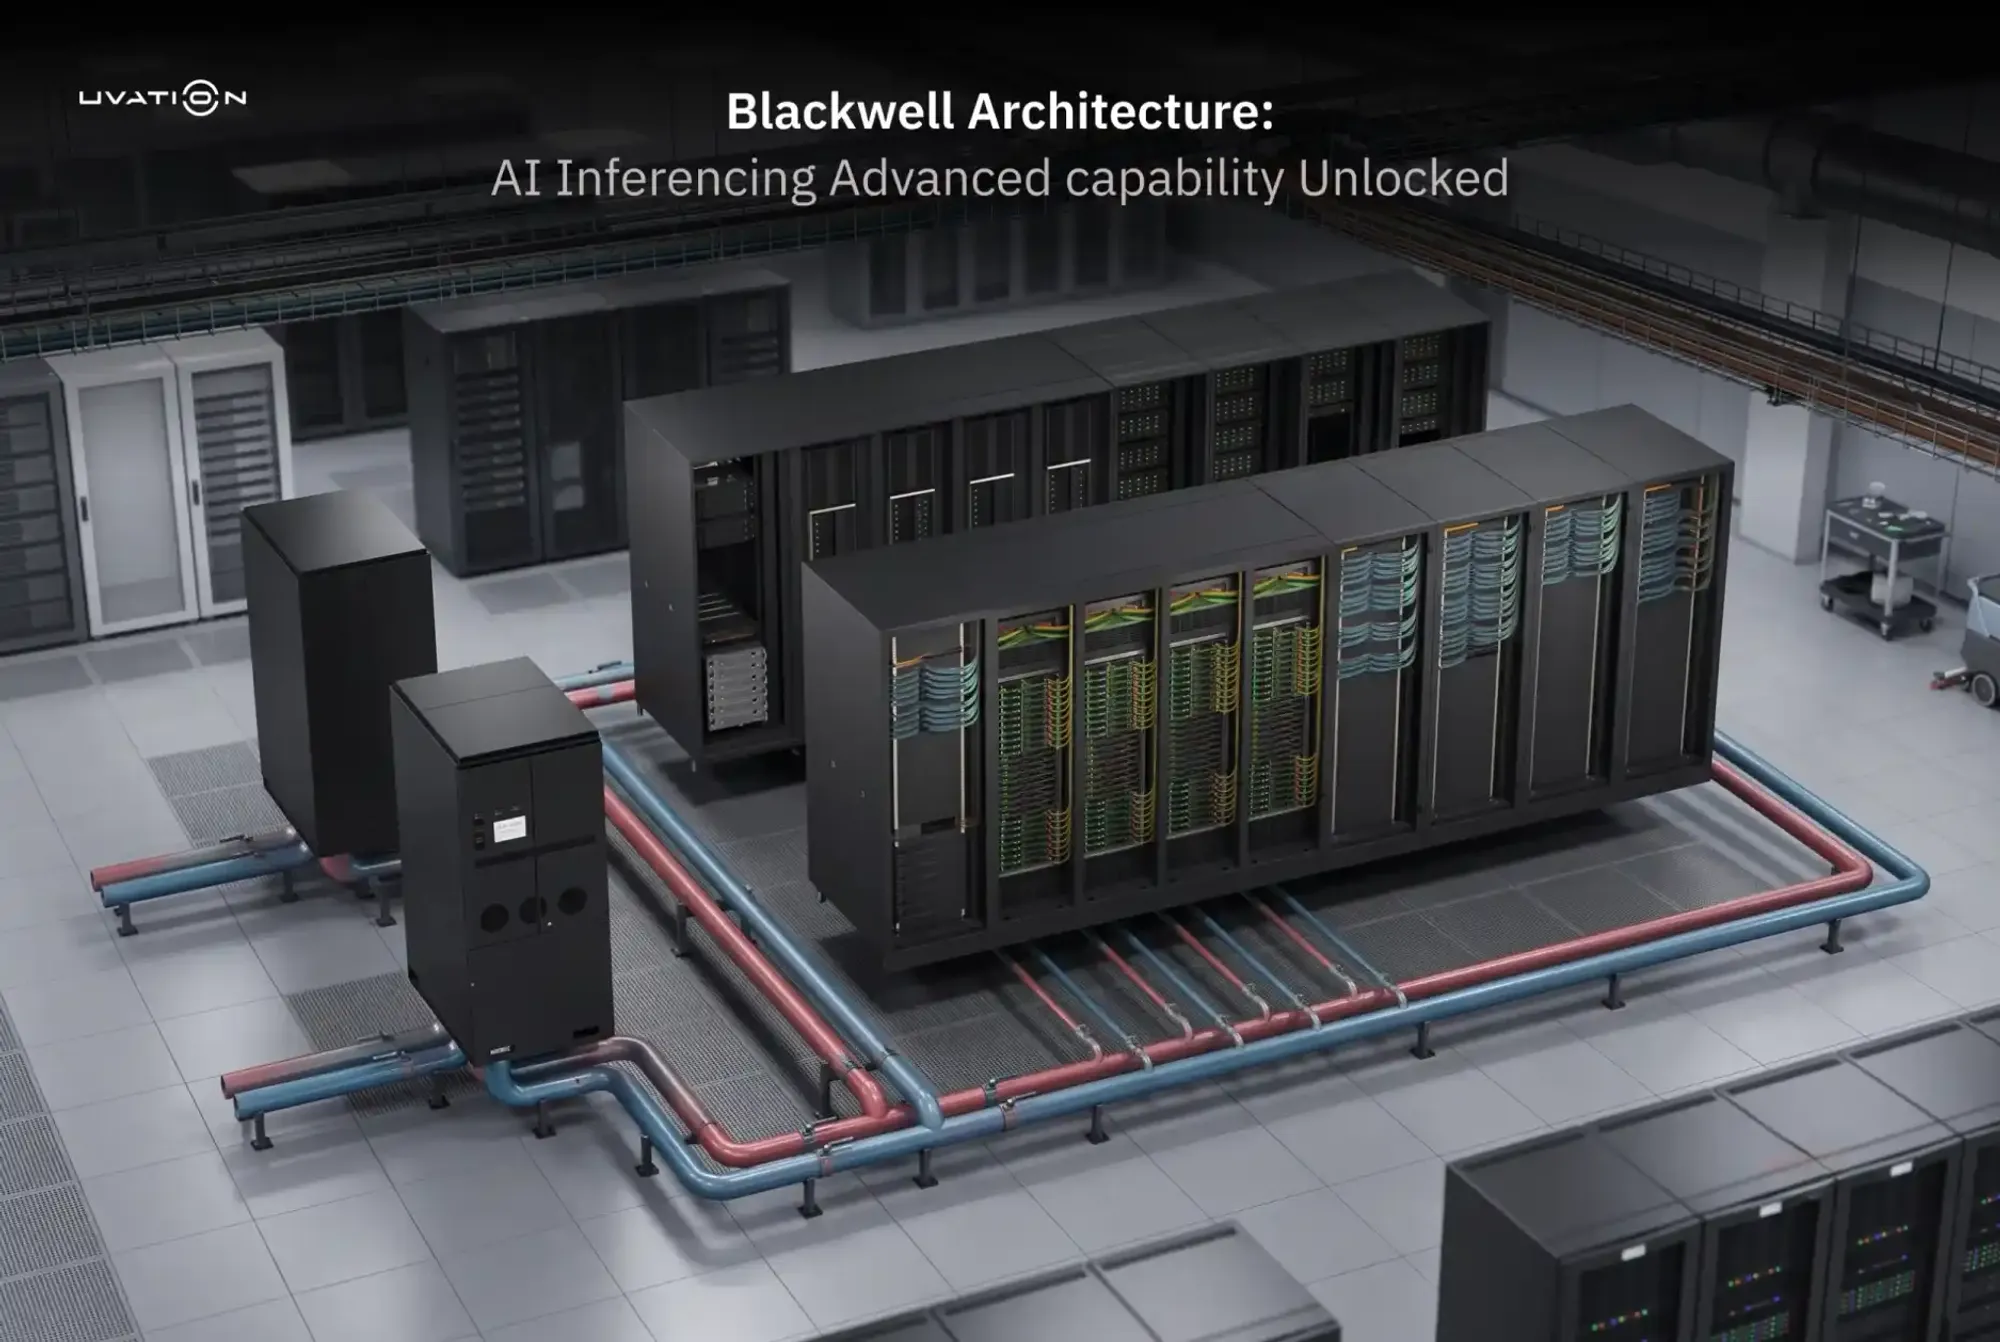
Generative AI tools like ChatGPT and Stable Diffusion are revolutionizing industries from healthcare to automotive. These models, with trillions of parameters, are pushing the boundaries of what's possible. However, as AI grows, a challenge emerges: AI inferencing. While training massive models gets the headlines, the real bottleneck lies in inference—the real-time execution of these models in real-world applications. Traditional hardware struggles to keep up with the growing computational demands of real-time AI, causing energy inefficiency, latency, and scalability constraints. Older GPUs, despite being powerful, fall short under these conditions, making applications like live video analysis or medical diagnostics slow and costly.
Subscribe to our Newsletter