
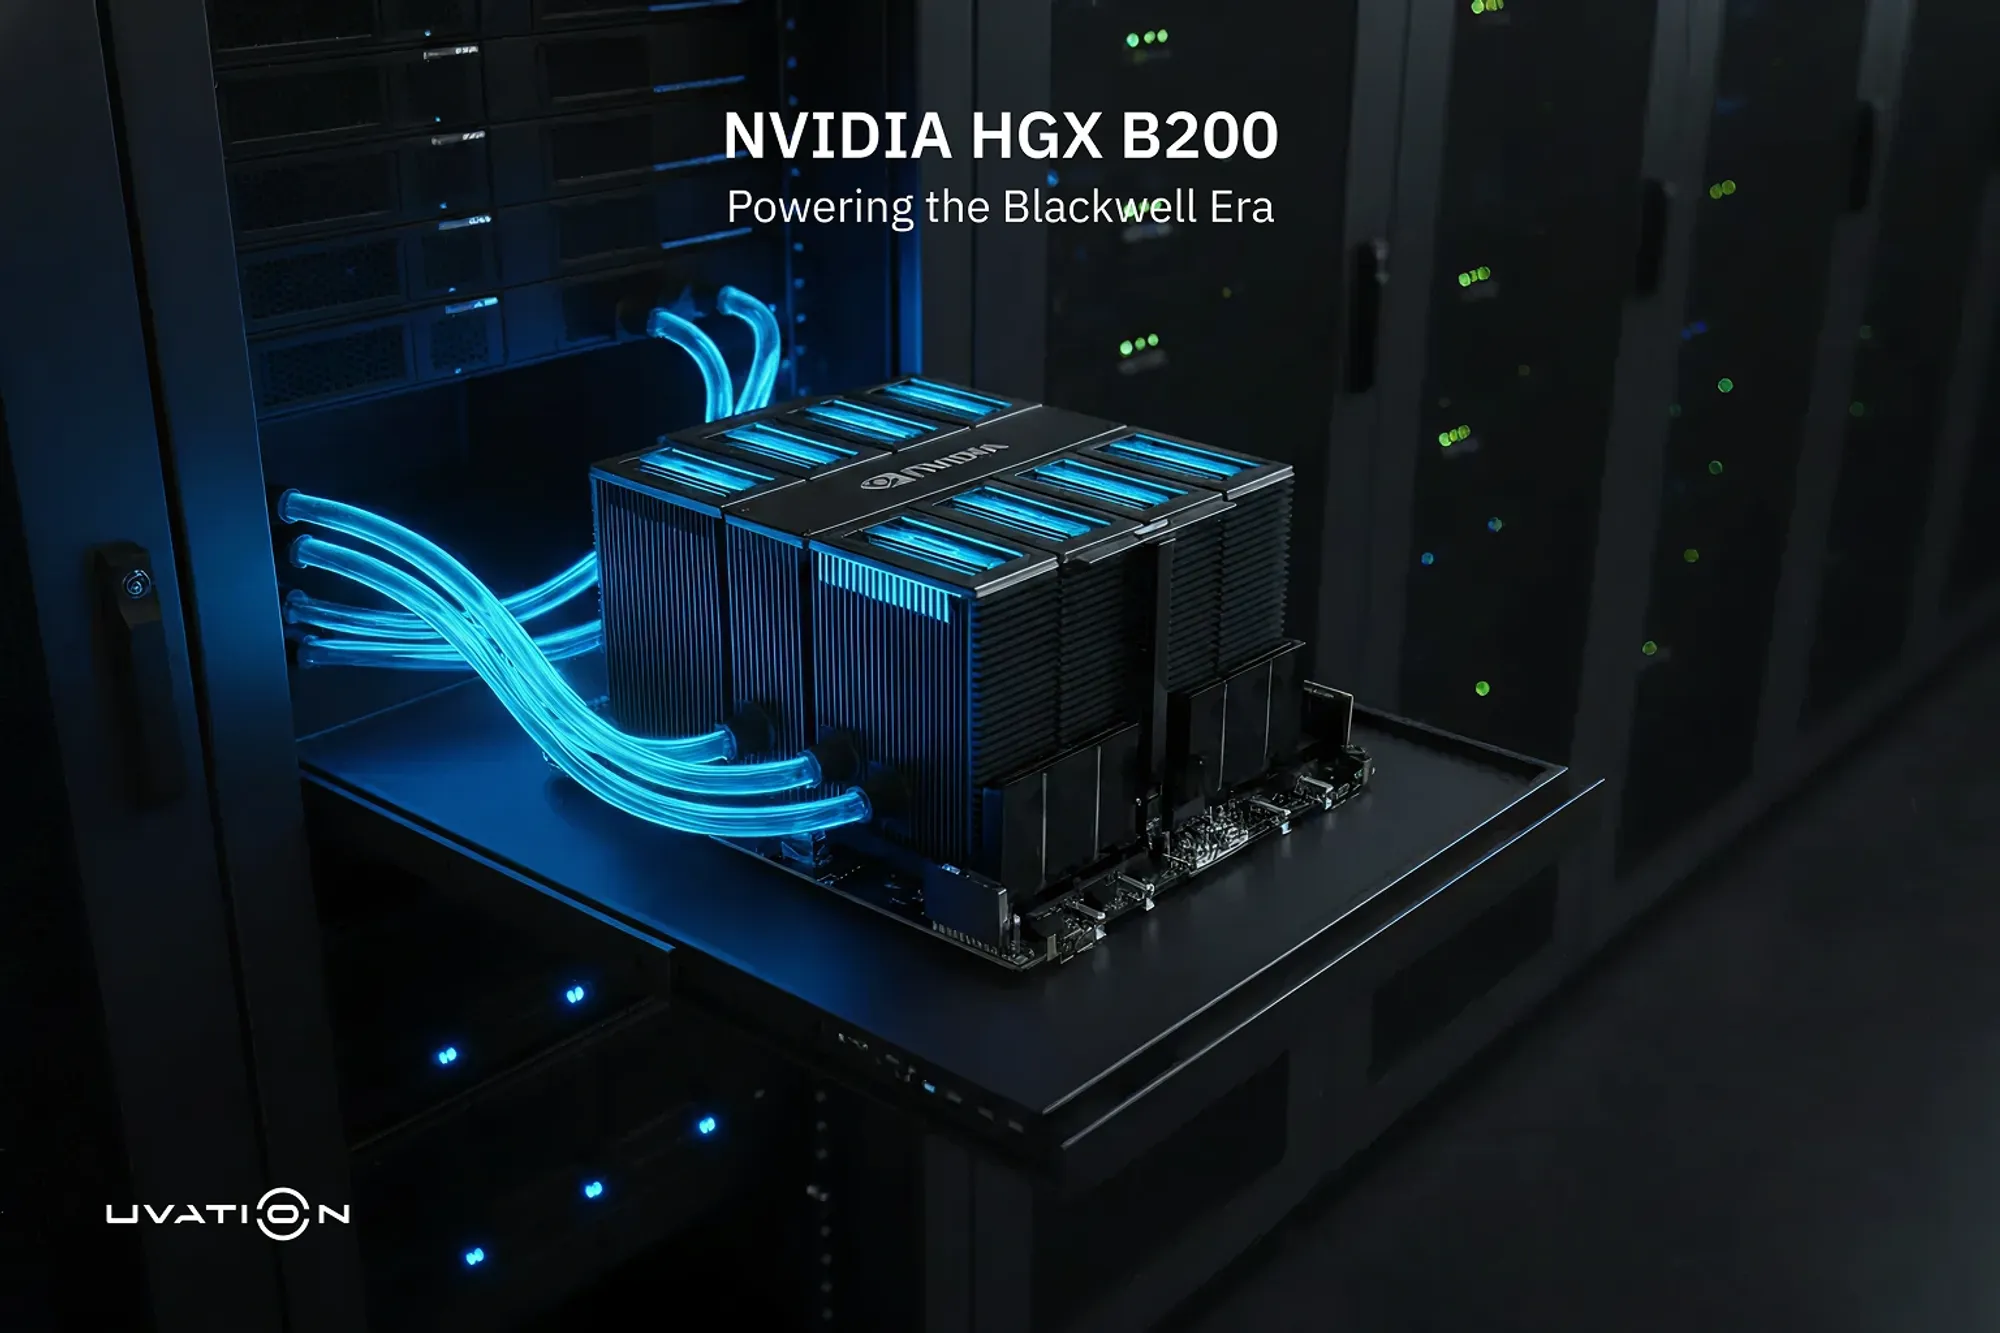
The NVIDIA HGX B200 is an eight-GPU platform engineered on the Blackwell architecture to handle the rigours of large-scale AI training and continuous inference. It integrates HBM3e memory, providing nearly 1.4 TB of capacity per baseboard, and utilises fifth-generation NVLink technology to deliver an immense 14.4 TB/s of GPU-to-GPU bandwidth. These enhancements facilitate up to 15x higher inference throughput and 3x faster training than previous Hopper-based systems. Crucially, the HGX B200 addresses data centre constraints by improving rack-scale efficiency and reducing energy intensity. By supporting low-precision formats like FP4 and FP8, it accelerates modern workloads while maintaining software compatibility. Essentially, the platform acts like a high-speed transit hub, where massive data stores and lightning-fast interconnects ensure information flows without the bottlenecks of traditional traffic.
Subscribe to our Newsletter