Information Technology

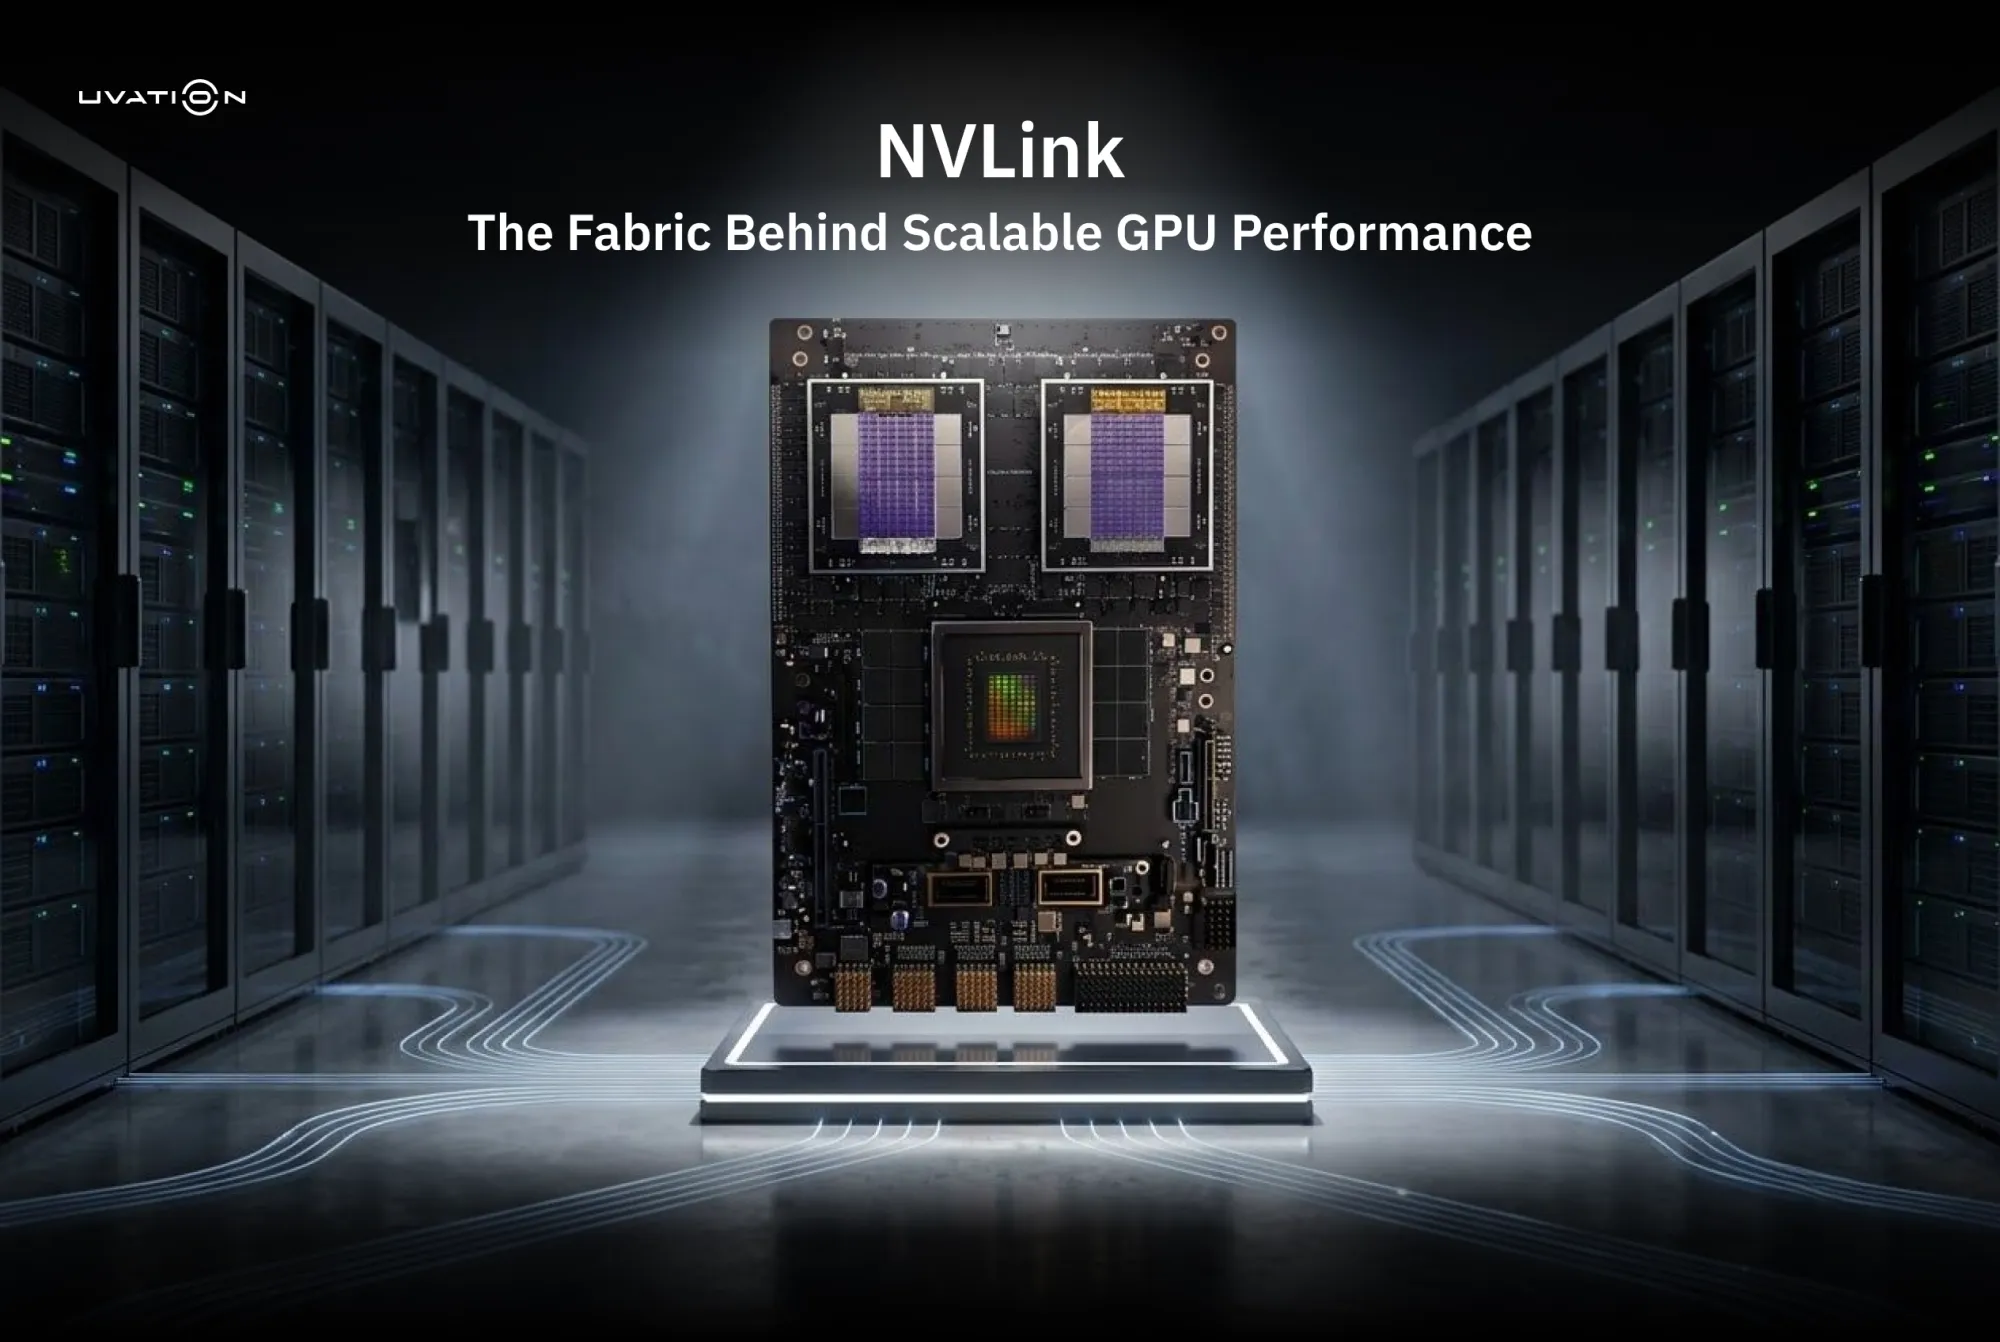
NVIDIA NVLink solves a core bottleneck in multi-GPU AI and HPC systems: GPUs can compute faster than PCIe can move data between them. By enabling direct, high-bandwidth GPU-to-GPU communication, NVLink reduces latency, speeds up synchronization, and lets large models or datasets span multiple GPUs more efficiently. The article explains how NVLink has evolved from early point-to-point links to rack-scale fabrics powered by NVLink Switch. It also compares where PCIe is still sufficient and where NVLink becomes necessary—typically when workloads use more than 2–4 GPUs, require tight synchronization, or exceed single-GPU memory. For H200 and B200 systems, NVLink improves training speed, inference latency, memory pooling, and overall scaling economics. The key takeaway: NVLink is essential for large AI and HPC workloads, but unnecessary for smaller models or light inference.
Subscribe to our Newsletter